
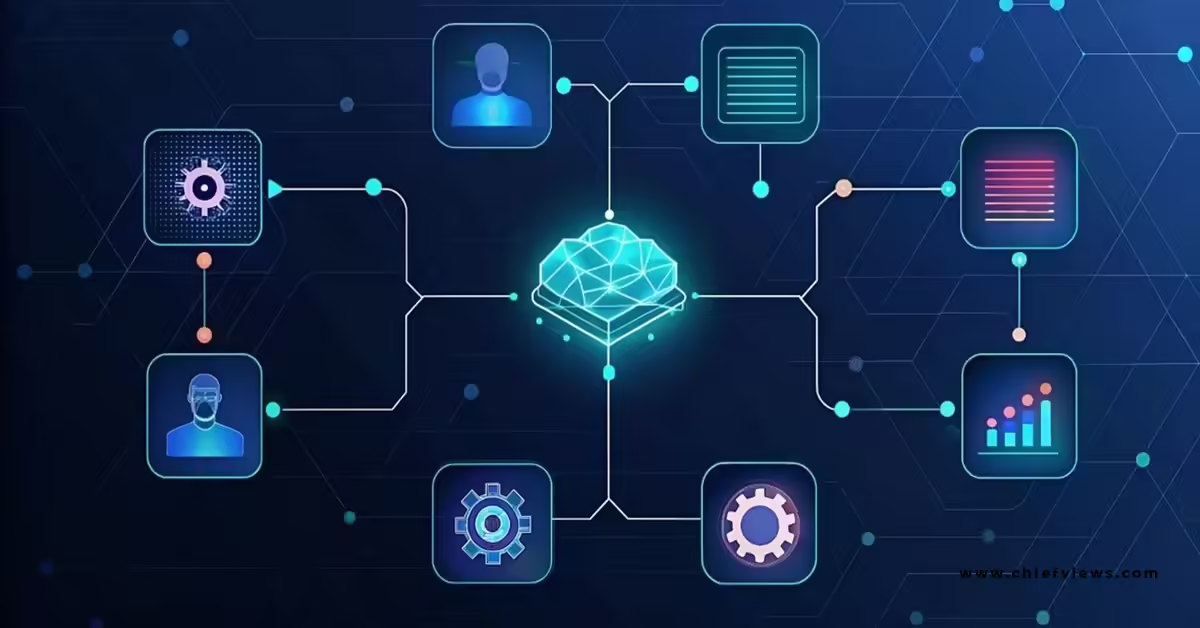
Enterprise AI data governance best practices start with treating data as the real control surface for every model, agent, and decision system you deploy. Skip the upstream work and even the strongest infrastructure collapses under poor lineage, inconsistent quality, and untracked access. Get the governance right and the models stay reliable, auditable, and useful at scale.
Here’s the quick view of what enterprise AI data governance best practices actually deliver in 2026:
- Complete inventory and sensitivity classification of every dataset that feeds AI systems.
- End-to-end lineage and provenance so you can reconstruct how any output was produced.
- Policy-as-code enforcement that travels with the data rather than sitting in a binder.
- Continuous quality and drift monitoring instead of one-time audits.
- Clear ownership and federated stewardship that keeps central standards without creating bottlenecks.
In my experience, the organizations that treat governance as an enabler rather than a gatekeeper are the ones that move from pilot to production without constant fire drills. The rest keep discovering the same data problems after the model is already live.
Why Traditional Data Governance Falls Short for AI
Classic data governance was built for batch reporting and structured warehouses. AI changes the game. Models and agents pull data in real time, generate synthetic copies, embed it into vectors, and pass it through retrieval pipelines. A single prompt can surface regulated information that never should have left its original boundary.
What usually happens is this: a data catalog exists, policies were written two years ago, and everyone assumes the controls still apply. Then an agent starts retrieving customer records or source code because the access rules were never enforced at query time. The gap between documented policy and runtime reality is where most AI governance programs fail.
Frameworks such as the NIST AI Risk Management Framework and ISO/IEC 42001 give clear reference points. They emphasize inventory, mapping, measurement, and continuous management across the full AI lifecycle. Gartner’s AI TRiSM model adds the technical enforcement layer that turns those principles into operational controls.
This work sits at the foundation of broader CIO strategies for building enterprise AI infrastructure. Without governed data, the hybrid architectures and placement decisions discussed in that strategy never deliver reliable outcomes.
Core Pillars of Enterprise AI Data Governance Best Practices
Start with inventory and classification. You cannot govern what you have not catalogued. Build a living inventory that covers structured, unstructured, and AI-generated data. Apply sensitivity labels that travel with the data and drive access decisions.
Lineage and provenance come next. Capture source, transformations, embeddings, prompts, and outputs. Graph-based lineage that updates automatically is far more useful than static documentation written after the fact.
Access and identity must be fine-grained. Treat every model and agent as a distinct principal with its own credentials and least-privilege permissions. Session-level controls are no longer enough when agents chain multiple tools and data sources.
Quality and monitoring have to be continuous. Define thresholds for completeness, accuracy, and representativeness before data reaches a model. Monitor for drift in both the source data and the model outputs. Automated alerts beat quarterly reviews every time.
Ownership and accountability close the loop. Assign domain stewards who understand the business context and can declare data contracts programmatically. Central teams set standards; domain teams execute them. This federated model scales without creating a single point of delay.
Step-by-Step Action Plan for Enterprise AI Data Governance
- Run a focused AI data inventory. List every dataset, pipeline, vector store, and prompt log currently used by AI systems. Tag each by sensitivity, ownership, and regulatory status. Prioritize the highest-risk and highest-value sources first.
- Map lineage for the top use cases. Choose three production or near-production AI applications. Trace data from original source through every transformation to the final output. Document gaps and fix the most critical missing links.
- Define risk-tiered policies. Create clear rules for what data classes can enter which AI tools or agents. Distinguish public, internal, confidential, and restricted. Make the rules enforceable through policy-as-code rather than manual review.
- Stand up runtime controls. Implement query-level or request-level enforcement so every agent action is evaluated against current policy before execution. Pair this with identity management that treats agents as first-class principals.
- Establish continuous quality gates. Set measurable thresholds for data entering training or retrieval pipelines. Automate checks and block or quarantine data that fails. Review the thresholds quarterly as use cases evolve.
- Assign stewards and create a lightweight governance forum. Name domain owners for the critical data products. Form a small cross-functional group (data, security, legal, business) that meets monthly to resolve exceptions and update standards.
- Instrument observability and audit trails. Capture who accessed what, when, and for which AI purpose. Retain the evidence in a form that supports both operational debugging and regulatory reconstruction.
This sequence keeps the work practical. Most teams that try to govern everything at once stall. Start with the data that already feeds live AI systems and expand outward.
Comparison of Governance Approaches for AI Data
| Approach | Best For | Strengths | Trade-offs | 2026 Fit |
|---|---|---|---|---|
| Centralized Committee | High-risk regulated environments | Strong consistency, clear accountability | Slow decisions, bottleneck risk | Early-stage or heavily regulated sectors |
| Federated Stewardship | Multi-domain enterprises | Scales with business units, domain expertise | Requires strong central standards | Most mature enterprise programs |
| Policy-as-Code + Runtime | High-volume agent and GenAI workloads | Real-time enforcement, auditability | Needs technical maturity and tooling | Production AI at scale |
| Catalog-Only | Discovery and documentation | Low barrier to start | Weak enforcement, outdated quickly | Temporary bridge, not long-term solution |
Federated models paired with runtime enforcement are emerging as the practical center for most U.S. enterprises balancing speed and control.
Common Mistakes and How to Fix Them
Treating governance as a one-time documentation exercise. Policies written once and never enforced create a false sense of security. Fix: move critical rules into code and test them continuously.
Building pipelines after the model is already trained. Data requirements surface late and force costly rework. Fix: design pipelines and quality gates as part of the initial use-case definition.
Ignoring AI-generated and synthetic data. These new data types often escape traditional classification. Fix: extend inventory and retention rules to cover generated outputs and embeddings from day one.
Centralizing every approval. Business teams route around slow gates and create shadow data flows. Fix: set clear standards centrally and push day-to-day decisions to domain stewards with automated guardrails.
Focusing only on access control while skipping lineage and quality. You can lock the doors and still feed the model garbage. Fix: treat lineage, quality, and access as equal pillars.
Underestimating cultural resistance. Technical controls fail when people do not understand why the rules exist. Fix: tie governance metrics to business outcomes and invest in basic data literacy for the teams that create and consume AI outputs.
Key Takeaways
- Inventory and classify AI-relevant data before expanding model deployments.
- Capture end-to-end lineage so every output can be reconstructed.
- Enforce policies at runtime rather than relying on periodic reviews.
- Assign clear domain ownership while keeping enterprise standards consistent.
- Monitor quality and drift continuously, not just at project kickoff.
- Treat agents and models as distinct identities with least-privilege access.
- Link governance work directly to the broader infrastructure strategy so data readiness and compute decisions stay aligned.
Strong enterprise AI data governance best practices turn data from a hidden liability into a reliable operating asset. Begin with the data already feeding your highest-value AI systems, close the lineage and quality gaps, and expand the controls as new use cases appear. That discipline keeps models trustworthy and the rest of the AI stack productive.
FAQs
What are the first practical steps in enterprise AI data governance best practices?
Start with an inventory of every dataset and pipeline currently used by AI systems, then map lineage for the top three use cases. Define risk-tiered access rules and move the most critical policies into enforceable code.
How do enterprise AI data governance best practices support larger infrastructure decisions?
They ensure the data feeding hybrid and multi-cloud environments is classified, quality-checked, and traceable. Without that foundation, even well-designed compute and placement strategies deliver unreliable results.
Why do many AI data governance programs fail to keep pace with production systems?
Most remain stuck in documentation mode while agents and models operate in real time. Runtime enforcement, continuous monitoring, and federated ownership close the gap between policy and actual data movement.

