
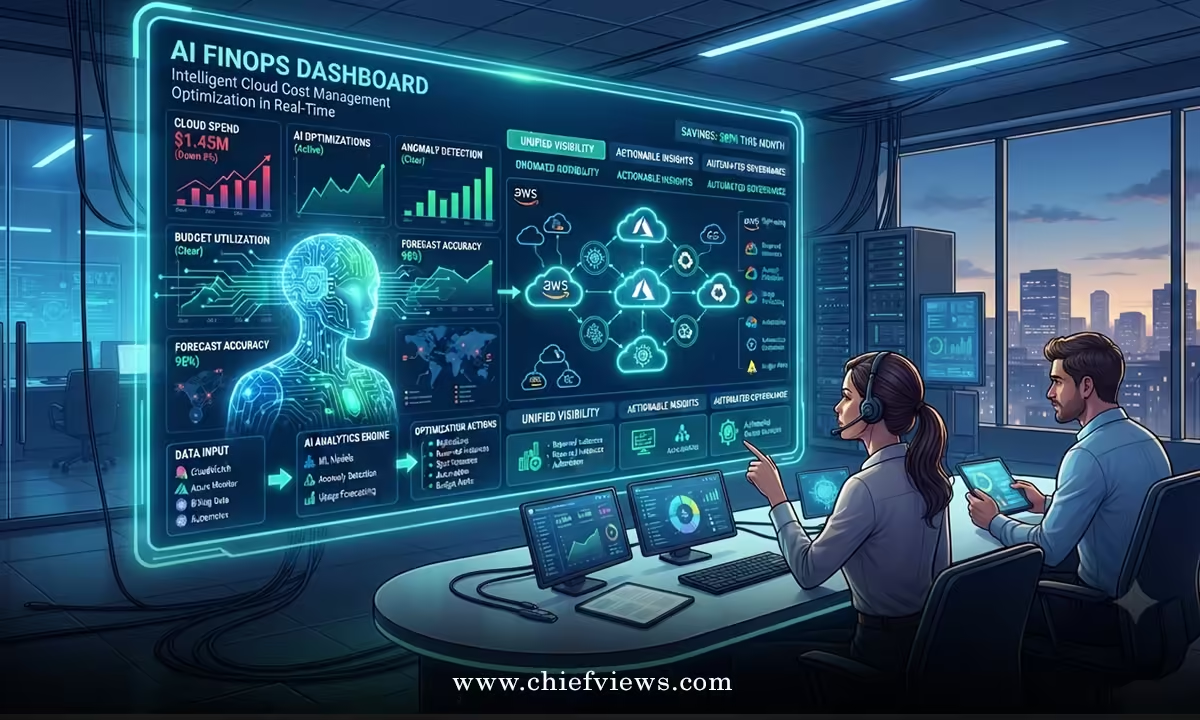
AI FinOps best practices turn runaway token bills and opaque agent costs into a managed, value-driven discipline. In 2026 nearly every FinOps team already tracks AI spend. The difference between the leaders and everyone else is how rigorously they apply the practices below.
Quick overview of what works right now:
- Full visibility and attribution of every AI call by team, feature, and model
- Model routing and prompt caching as the highest-leverage cost levers
- Unit economics (cost per inference, cost per successful outcome) instead of raw spend
- Chargebacks and real-time budgets that change behavior
- A clear maturity path from crawl to continuous optimization
The FinOps Foundation’s 2026 State of FinOps report shows 98 percent of practitioners now manage AI spend, up from 31 percent just two years earlier. AI cost management ranks as the single most desired skillset. Yet most organizations still estimate 20–30 percent of that spend as pure waste. The gap is operational, not technical.
Why traditional FinOps is not enough for AI
Cloud FinOps grew up around VMs, storage, and predictable reservations. AI introduces token volatility, agent loops, context bloat, and model-choice decisions that can swing costs by orders of magnitude on a single request.
One poorly designed agentic workflow can burn more in a weekend than a traditional cloud service costs in a month. Without instrumentation at the call level, finance sees only a growing line item and engineering sees only “the model is working.” That disconnect is exactly why AI FinOps best practices exist.
These practices sit downstream of the broader capital discipline outlined in the CFO guide to balancing AI ROI with cost optimization. Once the portfolio and outcome metrics are set, AI FinOps supplies the day-to-day control plane that keeps unit costs falling while value rises.
Core AI FinOps best practices that deliver results
1. Instrument every call for attribution
Tag at the point of invocation. Feature, team or cost center, model, and use-case ID minimum. Retroactive tagging fails. Route all LLM and agent traffic through a gateway or proxy that enforces the tags. Within days you will see which features actually drive the bill.
2. Route to the lowest-cost capable model
Frontier models are expensive. Most tasks do not need them. Classification, extraction, summarization, and simple generation run fine on mid-tier or open-weight models. Enforce routing rules at the gateway. Mature teams report 25–40 percent lower unit costs from this single change without quality loss on the majority of workloads.
3. Cache aggressively at three layers
Exact-match caching for identical requests. Semantic caching for near-duplicates. Native prompt caching for shared system prompts and long context prefixes. Provider prompt caching alone can cut input token costs by up to 90 percent on stable prefixes. Stack all three and the savings compound.
4. Track unit economics, not just total spend
Cost per inference, cost per successful outcome, cost per 1,000 tokens, and GPU utilization are the metrics that matter. Aggregate bills hide waste. Unit metrics surface it. Set targets per use case and review them monthly.
5. Move from showback to chargeback
Show teams their spend first. Then charge it back to the business unit once the use case is in production. Central budgets stay for true experiments. Behavior changes the moment the cost lands on someone’s P&L.
6. Set hard and soft guardrails
Feature-level and team-level budgets with alerts. For high-risk agentic flows, add step limits and tool budgets that stop runaway loops. Hard stops for sandboxes; graceful degradation (auto-downgrade model) for production.
Comparison of AI FinOps maturity stages
| Maturity Stage | Primary Focus | Key Actions | Typical Outcomes |
|---|---|---|---|
| Crawl | Visibility | Tagging, basic dashboards, anomaly alerts | Know where the money goes |
| Walk | Control & optimization | Model routing, caching, per-team budgets, chargebacks | 20–30 % unit cost reduction |
| Run | Continuous value | Automated routing, real-time cost-per-outcome, self-funding reinvestment | Predictable costs + rising ROI |
Step-by-step action plan to implement AI FinOps best practices
- Stand up a lightweight AI gateway or observability layer that captures cost metadata on every call. Do this before you chase savings.
- Inventory the top 10 consuming features or agents by current spend. Attach a primary outcome metric to each.
- Implement model routing rules for the highest-volume simple tasks. Measure quality and cost for two weeks.
- Enable prompt caching and exact-match caching on the heaviest context workloads.
- Publish a weekly cost-per-outcome report to the owners of those top 10 features.
- Convert the stable production use cases to business-unit chargeback. Keep a small central experiment budget.
- Review the portfolio every quarter. Reallocate savings into higher-ROI AI bets. This closes the loop with the capital allocation process described in the CFO guide to balancing AI ROI with cost optimization.
In my experience, teams that complete steps 1–4 in the first 45 days already see meaningful burn-rate reductions and, more importantly, regain forecasting credibility with the CFO.
Common mistakes and how to fix them
Mistake: Tracking only the provider invoice. Fix: Instrument at the application layer so you know feature and team.
Mistake: Letting every developer pick the most powerful model by default. Fix: Gateway-enforced routing with clear quality thresholds.
Mistake: Treating caching as a nice-to-have. Fix: Make it mandatory for any prompt longer than a few hundred tokens or any repeated workflow.
Mistake: No ownership. Fix: Name a single cost owner for AI spend and give them a dotted line to finance.
Mistake: Optimizing for cost alone. Fix: Pair every cost metric with an outcome metric. Cheap and useless is still waste.
Key Takeaways
- 98 percent of FinOps teams already manage AI spend; the winners treat it as a distinct discipline with its own levers.
- Visibility and attribution at the call level are non-negotiable starting points.
- Model routing and multi-layer caching deliver the fastest, largest unit-cost reductions.
- Unit economics (cost per inference or successful outcome) beat aggregate spend reports every time.
- Chargebacks change behavior faster than policy memos.
- AI FinOps works best when it feeds a larger capital framework such as the CFO guide to balancing AI ROI with cost optimization.
- Continuous review and reinvestment of savings turn cost control into a growth engine.
Start with instrumentation and routing. Everything else becomes measurable once you can see the real unit economics. Do that well and AI stops being a budget surprise and starts becoming a managed, high-return investment.
FAQs
What is the single highest-leverage AI FinOps best practice most teams miss?
Model routing. Most requests do not need frontier models. Enforcing the right model for the task at the gateway routinely cuts 25–40 percent of unit costs with minimal quality impact.
How do AI FinOps best practices connect to broader ROI discipline?
They supply the operational control layer that makes the strategic framework in the CFO guide to balancing AI ROI with cost optimization actually work day to day—turning portfolio decisions into measurable unit-cost improvements.
How long does it take to see results from AI FinOps best practices?
Visibility and basic routing usually deliver measurable savings inside 30–45 days. Full chargeback and continuous optimization mature over one to two quarters.

